careers-lead-image

Careers

At Amazon, we believe that scientific innovation is essential to being the most customer-centric company in the world. Our scientists' ability to have an impact at scale allows us to attract some of the brightest minds across diverse fields including artificial intelligence, robotics, computer vision, economics, and sustainability. Join us in pioneering solutions to complex challenges that not only delight our customers but also help define the future of technology.
  • The program is designed for academics from universities around the globe who want to work on large-scale technical challenges while continuing to teach and conduct research at their universities.
  • The program offers recent PhD graduates an opportunity to advance research while working alongside experienced scientists with backgrounds in industry and academia.
  • Our internship roles span research areas to provide hands-on experience working alongside world-class scientists and engineers to advance the state of the art in your field.
658 results found
  • (Updated 39 days ago)
    Are you passionate about giving customers the richest, most inspiring experience in their shopping journey? Do you like to dive deep to understand how customer-centric solutions drive measurable results? Do you enjoy working closely with the business and software engineers to design rigorous experiments, build the data infrastructure behind them, and translate results into decisions? You are in the right place! Come join our Prime & Marketing Analytics and Science (PRIMAS) team, where your work will directly impact millions of customers. The EU Marketing & Prime organization is looking for a Data Scientist to join the PRIMAS team. This role sits at the intersection of applied statistics and large-scale analytics — you'll design experiments and causal models, and also own the data pipelines, metrics, and reporting infrastructure that make those results usable across the business. The PRIMAS team provides a comprehensive understanding of customer segments, affinities, and lifetime value. We use data science tools and advanced statistical techniques to study customer purchase and engagement behaviors, and generate actionable insights on where, when, and how we deliver products and programs to customers. We help increase customer engagement, sales, and marketing efficiency, and our systems are built entirely in-house on automated large-scale analytics infrastructure. You will design, launch, and measure experiments across marketing channels (SEM/SEO, Affiliates, Display, Social, Mobile, Email, Onsite, etc.), engagement products, and customer segments. You will improve our understanding of customer behavior, run rigorous power and minimum detectable effect (MDE) analyses to size experiments correctly, and build the causal and conversion models that value and target our marketing — then build the pipelines and dashboards that keep those signals flowing reliably to stakeholders and downstream systems. You will work at the forefront of consumer analytics, tackling some of the hardest measurement problems in the industry alongside strong scientists, statisticians, and software engineers. Key job responsibilities 1. Design and implement scalable, statistically rigorous experiments (A/B, geo, holdout, quasi-experiments) to measure marketing incrementality across channels. 2. Perform power analysis and minimum detectable effect (MDE) calculations to determine experiment sample sizes, durations, and design trade-offs before launch. 3. Build causal and treatment-effect models that produce conversion and valuation signals consumed by downstream bidding and budgeting systems. 4. Building the ETL, metric definitions, and datasets that make results scalable, extensible, and repeatable rather than one-off analyses. 5. Develop measurement frameworks that quantify the true, platform-independent contribution of marketing over time, and build the dashboards and reporting that keep those metrics visible to the business. 6. Apply statistical, mathematical, and machine learning techniques to solve ambiguous business problems where the right approach isn't obvious. 7. Analyze experiment results for validity — inspecting distributions, checking for sample ratio mismatch, exploring covariate balance, and tracking down the source of anomalies. 8. Communicate experiment design, results, and trade-offs clearly to business and leadership audiences, including inputs into business reviews, and influence decisions and technical direction across teams. 9. Establish scalable, repeatable processes and best practices for experiment design, data modeling, and analysis.
  • (Updated 13 days ago)
    Are you passionate about giving customers the richest, most inspiring experience in their shopping journey? Do you like to dive deep to understand how customer-centric solutions drive measurable results? Do you enjoy working closely with the business and software engineers to design rigorous experiments, build the data infrastructure behind them, and translate results into decisions? You are in the right place! Come join our Prime & Marketing Analytics and Science (PRIMAS) team, where your work will directly impact millions of customers. The EU Marketing & Prime organization is looking for a Data Scientist to join the PRIMAS team. This role sits at the intersection of applied statistics and large-scale analytics — you'll design experiments and causal models, and also own the data pipelines, metrics, and reporting infrastructure that make those results usable across the business. The PRIMAS team provides a comprehensive understanding of customer segments, affinities, and lifetime value. We use data science tools and advanced statistical techniques to study customer purchase and engagement behaviors, and generate actionable insights on where, when, and how we deliver products and programs to customers. We help increase customer engagement, sales, and marketing efficiency, and our systems are built entirely in-house on automated large-scale analytics infrastructure. You will design, launch, and measure experiments across marketing channels (SEM/SEO, Affiliates, Display, Social, Mobile, Email, Onsite, etc.), engagement products, and customer segments. You will improve our understanding of customer behavior, run rigorous power and minimum detectable effect (MDE) analyses to size experiments correctly, and build the causal and conversion models that value and target our marketing — then build the pipelines and dashboards that keep those signals flowing reliably to stakeholders and downstream systems. You will work at the forefront of consumer analytics, tackling some of the hardest measurement problems in the industry alongside strong scientists, statisticians, and software engineers. Key job responsibilities 1. Design and implement scalable, statistically rigorous experiments (A/B, geo, holdout, quasi-experiments) to measure marketing incrementality across channels. 2. Perform power analysis and minimum detectable effect (MDE) calculations to determine experiment sample sizes, durations, and design trade-offs before launch. 3. Build causal and treatment-effect models that produce conversion and valuation signals consumed by downstream bidding and budgeting systems. 4. Building the ETL, metric definitions, and datasets that make results scalable, extensible, and repeatable rather than one-off analyses. 5. Develop measurement frameworks that quantify the true, platform-independent contribution of marketing over time, and build the dashboards and reporting that keep those metrics visible to the business. 6. Apply statistical, mathematical, and machine learning techniques to solve ambiguous business problems where the right approach isn't obvious. 7. Analyze experiment results for validity — inspecting distributions, checking for sample ratio mismatch, exploring covariate balance, and tracking down the source of anomalies. 8. Communicate experiment design, results, and trade-offs clearly to business and leadership audiences, including inputs into business reviews, and influence decisions and technical direction across teams. 9. Establish scalable, repeatable processes and best practices for experiment design, data modeling, and analysis.
  • (Updated 29 days ago)
    Are you ready to revolutionize the future of aerial delivery? Join our pioneering team working on autonomous drone technology that will transform how Amazon delivers to customers. As a Manager III, Applied Science for our Perception team, you'll lead scientists and engineers building world-class machine learning models and computer vision and new frontier model based systems that enable drones to safely navigate complex environments. In this high-impact role, you'll guide the development of perception systems combining radar, machine learning, and distributed computing to solve unprecedented challenges in autonomous flight. Your work will directly shape the future of Amazon's drone delivery service, bringing innovative solutions to customers while pushing the boundaries of what's possible in autonomous systems technology. Key job responsibilities Lead and mentor a team of scientists and software engineers developing advanced perception systems that integrate computer vision, machine learning algorithms, and detect-and-avoid capabilities for autonomous drones Define and drive the technical vision and roadmap for perception technology, making strategic architectural decisions that balance current delivery needs with long-term innovation goals Collaborate with cross-functional teams including hardware engineers, autonomy specialists, and product stakeholders to deliver scalable, distributed systems that meet rigorous safety and performance requirements Establish audit mechanisms and metrics to track system performance, model accuracy, and team progress against goals, using data-driven insights to continuously improve customer experience Build and grow an inclusive, high-performing team through effective hiring, mentoring, and career development while fostering a culture of innovation and technical excellence About the team The Perception team is at the heart of Amazon's autonomous drone delivery initiative, developing the advanced computer vision and machine learning systems that enable safe, reliable flight operations. Our team tackles fascinating challenges at the intersection of radar technology, distributed computing, and real-time detection algorithms, creating solutions that have never been built before. We work in an innovative, collaborative environment where every scientists and engineer's contribution directly impacts the future of delivery technology. As we scale Amazon's drone delivery to new locations, you'll help shape both the technical direction and team culture that will define this transformative service for years to come.
  • US, CA, Palo Alto
    Job ID: 10534443
    (Updated 37 days ago)
    Alexa for Shopping (Rufus) is Amazon's new AI-powered shopping assistant that combines the capabilities of Rufus and Alexa+ to provide a more personalized and intelligent shopping experience. We are building the future of AI-powered commerce, where every customer interaction is conversational, personalized, and proactive. We are searching for pioneers who are passionate about technology, innovation, and customer experience, and are ready to make a lasting impact on the industry. In this role, you will be managing a team working on Large Language Model (LLM) and/or Vision-Language Model (VLM) post-training and alignment for new shopping experiences. You will set the roadmap and vision for science investments across multiple new customer experiences and to optimize existing experiences to deliver the most helpful, accurate, and fastest AI shopping assistant in the industry The ideal candidate is deeply steeped in LLM-based architectures, post-training techniques (RLHF, DPO, fine-tuning), and multi-agent systems. They are passionate about applied science, working back from customer experience to define what matters, and building teams that ship production AI at scale. You’ll be working with talented scientists, engineers, and product managers to innovate on behalf of our customers. If you’re fired up about being part of a dynamic, driven team, then this is your moment to join us on this exciting journey!
  • CA, BC, Vancouver
    Job ID: 10557195
    (Updated 26 days ago)
    Alexa Connections is on a mission to become the world's most trusted communication agent, spanning calls, text, email, and the ever-expanding surfaces where people connect. We're building intelligence that keeps customers connected effortlessly while putting their trust and privacy first. As an Applied Scientist, you'll help build the smartest communications agent for people, an agent that understands intent, context, and relationships, and that acts on a customer's behalf to make every interaction feel effortless and genuinely helpful Key job responsibilities You'll research, develop, and deploy the language intelligence that powers how people communicate, using and adapting large language models to understand intent, context, and the entities that matter in a conversation, the people, contacts, events, dates, and topics that tell the agent who and what a message is about. In practice, that means reframing classic NLP and named entity recognition as LLM-native tasks through instruction-tuning, in-context learning, and structured generation, and building agentic capabilities that reason over multi-turn conversations and act on them, from summarization and smart replies to coreference and context resolution grounded in a customer's relationships and history. You'll fine-tune, align, and optimize foundation models for the messiness of real communication data, informal text, code-switching, misspellings, transcribed speech, and multilingual content, and ground their outputs in customer context using retrieval-augmented generation and personalization so responses stay relevant and reliable. Throughout, you'll take models from research to production at scale, partnering with engineering and product teams to ship LLM-powered features used by millions every day, and define the evaluation frameworks that measure quality, faithfulness, latency, and customer impact while keeping trust and privacy first.
  • CA, ON, Toronto
    Job ID: 10564406
    (Updated 1 days ago)
    Are you a passionate scientist in the computer vision area who is aspired to apply your skills to bring value to millions of customers? Here at Ring, we have a unique opportunity to innovate and see how the results of our work improve the lives of millions of people and make neighborhoods safer. You will be part of a team committed to pushing the frontier of computer vision and machine learning technology to deliver the best experience for our neighbors. This is a great opportunity for you to innovate in this space by developing highly optimized algorithms that will work on scale. This position requires experience with developing Multi-modal LLMs and Vision Language Models. You will collaborate with different Amazon teams to make informed decisions on the best practices in machine learning to build highly-optimized integrated hardware and software platforms. Key job responsibilities - Participate in the design, development, evaluation, deployment and updating of data-driven models for computer vision applications. - Research and implement the state-of-the-art computer vision and Vision Language models algorithms. - Collaborate with product managers and engineering teams to design and implement computer vision and machine learning based features for Ring devices - Influence system design and product vision by making informed decisions on the selection of technology, data sources, algorithms, and sensors.
  • US, TX, Austin
    Job ID: 10517467
    (Updated 35 days ago)
    Are You Ready to Redefine How the World Receives Its Packages? What if your algorithms defined the most efficient path for millions of deliveries — every single day? At Amazon, we're building the science that makes that possible, and we're looking for exceptional scientists to help lead the way. The Last Mile Routing & Planning organization develops the software, algorithms, and tools that power the "magic" of home delivery. Our planning and routing intelligence systems drive billions of daily decisions — enabling safe, efficient, and frustration-free routes for drivers across the globe. What You'll Do In this role, you'll sit at the intersection of state-of-the-art research and real-world impact. You will: - Design and build algorithms that solve large-scale, complex logistics problems - Synthesize data from diverse sources to identify high-value business opportunities - Provide research direction and data-driven insights to guide strategic decisions - Translate complex technical approaches into clear communication for scientists, engineers, and business stakeholders - Partner closely with scientists and engineers in a collaborative, high-impact environment What You'll Work On We have an exciting and growing portfolio of research areas, including: - Routing for same-day and grocery deliveries - Planning for electric and autonomous vehicles - District-level and stop-level planning - Forecasting solutions for diverse delivery programs All of this is powered by the latest methods in Operations Research (OR), Machine Learning (ML), and Generative AI — at a truly global scale. Successful candidates will lead one or more of these problem spaces. What We're Looking For - Deep expertise in Operations Research and/or Machine Learning methods - Proven experience applying these methods to large-scale, real-world business problems - Ability to translate models into production-ready code in Python or Java - Strong communication skills — you can explain complex technical concepts to diverse audiences - A bias for action and an iterative mindset when tackling ambitious research challenges Why Amazon We're passionate about your growth. Whether you want to explore emerging technologies, take on broader scope, or accelerate your career trajectory, we'll invest in helping you get there. Our business is scaling fast — and so are the opportunities for the people who build it. If you're driven by the challenge of optimizing one of the world's most complex logistics systems and excited to see your work impact millions of customers daily, we'd love to hear from you. Key job responsibilities - Invent and design novel solutions for scientifically complex problem areas, and identify opportunities for invention within existing and new business initiatives - Deliver large-scale, high-impact solutions to complex problems in support of medium-to-large business goals - Shape the design of scientifically complex software systems, personally contributing significant portions of the critical scientific novelty - Apply mathematical optimization, machine learning, and Generative AI techniques to develop solution methodologies for in-house decision support tools and software - Research, prototype, simulate, and experiment with models — and actively participate in their production-level deployment in Python or Java - Engage with the broader scientific community by publishing research articles and participating in leading research conferences
  • US, CA, Sunnyvale
    Job ID: 10517288
    (Updated 62 days ago)
    We are looking for a Senior Inference Engineer to own inference for real-time multimodal conversational AI. This is a full-stack inference role: you will work across the entire path a model takes from research to production — shaping model architecture so it is servable, building the real-time runtime that serves it within hard latency budgets, and building the offline systems that train and reinforce it. You will operate at the boundary of Science and Inference, taking frontier-scale speech and audio models and making them run within real-time latency budgets on production hardware. You will co-design architectures with scientists to make them inference-friendly from inception, own the low-latency streaming serving path, and build the training and reinforcement-learning infrastructure that closes the loop. You will have the compute, data, and runway to solve problems that few teams in the world are positioned to tackle. As a Senior Engineer, you will own a significant area of the inference stack end to end, drive its technical execution, contribute to the team's roadmap, and work closely with scientists and hardware partners to ensure our models run fast enough to feel human in real time — and at a cost that makes them viable at scale. You may go deep in one of the areas below while contributing across the others. Key job responsibilities Model Architecture & Inference Co-Design • Partner with research scientists to make model architectures servable from inception — surfacing the latency, memory, and cost implications of architecture choices before they are locked in • Implement and optimize the inference path for large-scale multimodal models — attention and KV-cache mechanisms, multimodal/autoregressive decoding, and the compute primitives on the critical path Apply efficiency techniques across the stack — quantization (per-tensor/per-channel/per- group, INT8/FP8/BF16), speculative decoding, operator fusion, and paged KV-cache — and quantify their quality/latency trade-offs • Develop and tune high-performance kernels for critical operations where off-the-shelf implementations leave performance on the table, integrating them into production serving with minimal overhead • Profile end-to-end performance with tools such as Nsight Compute/Systems and roofline analysis to identify and eliminate bottlenecks in large-scale inference workloads Real-Time & Interactive Runtime • Own the real-time serving path for streaming multimodal conversational AI, meeting sub- second, streaming latency budgets under concurrent session load • Build and tune continuous batching, scheduling, and preemption to balance throughput against per-request latency SLAs for interactive workloads • Customize production serving frameworks (e.g., vLLM, PyTorch) for real-time streaming generative models that fall outside standard LLM serving patterns — sustained low-latency output under concurrent session load • Implement multi-GPU inference (tensor parallelism, collective communication) for latency- critical paths, and drive cost toward parity with existing production baselines • Establish latency, throughput, and cost benchmarking, and publish the operational metrics that gate deployment Offline Systems: Training, RL & Evaluation Infrastructure • Build and scale the offline inference systems behind post-training — high-throughput rollout generation and reward-model serving for reinforcement learning (RL/RLHF/RLAIF) • Ensure train/serve consistency — that the inference path used in RL and evaluation faithfully matches production online behavior (e.g., parity across sampling and logit processing) • Work with the evaluation team to enable offline inference that captures the quality dimensions unique to real-time conversation — latency sensitivity, audio quality, and interaction naturalness
  • US, WA, Bellevue
    Job ID: 10523945
    (Updated 39 days ago)
    Have you ever placed an order on Amazon and wondered how it got to you so fast? Behind that speed is a massive transportation network generating billions of data points daily. We need someone who can turn that data into clarity. Come join the Network Engineering, Scheduling and Technology (NEST) Science team within Amazon Transportation Services. We are looking for a Data Scientist who is equal parts data engineer, visualization architect, and analytical modeler. You will own the end-to-end build process for data-driven solutions: identifying business needs, developing simulation and optimization models, building computationally efficient analytical tools, and narrating results through compelling data storytelling. This is not a dashboard-building role. You will work at the intersection of large-scale data processing, advanced analytics (including simulation and optimization), and data visualization, building tools that allow stakeholders to explore millions of records interactively, uncover patterns in network performance, and make data-driven decisions with confidence. The ideal candidate is a data wizard who thrives on wrangling massive datasets, building predictive and prescriptive models, architecting performant query and aggregation pipelines, and crafting visualizations that communicate complex findings with precision and clarity. You will own the full lifecycle, from problem identification and data extraction through modeling and simulation to production-grade analytical applications that narrate results back to stakeholders. You will collaborate closely with scientists, engineers, and product managers Key job responsibilities - Own the end-to-end analytical lifecycle: identify stakeholder needs, frame problems, build models, and narrate results through data tools and visualizations - Design and build production-grade analytical tools, BI applications, and interactive data products that enable self-service exploration of very large transportation datasets (billions of records) - Develop and enhance simulation and optimization models (discrete event simulation, agent-based modeling, mathematical optimization) applied to network planning and transportation operations - Architect computationally efficient data pipelines and aggregation strategies that support responsive, real-time or near-real-time visualization at scale - Develop advanced data storytelling artifacts that communicate complex network dynamics, trends, and anomalies to technical and non-technical stakeholders - Build and maintain reusable visualization frameworks and libraries tailored to transportation network data (routing, scheduling, flow, capacity) - Work with large-scale data platforms (Redshift, Spark, S3, Athena) to extract, transform, and model data for analytical consumption - Develop code (Python, SQL, Scala) for data processing, statistical modeling, simulation, and building automated analytical workflows - Collaborate with Applied Scientists, Research Scientists, Software Engineers, and Product Managers to integrate analytical tools into broader planning and decision-support systems - Define and implement best practices for data visualization performance, including sampling strategies, level-of-detail rendering, and progressive loading for large datasets - Communicate findings, methodology, and recommendations through compelling written and verbal presentations to leadership and business customers About the team The Network Engineering, Scheduling, and Technology (NEST) Science Team prototype, build, and productionize mathematical models that reduce transportation cost and improve customer experience in Amazon's Middle Mile network. Equipped with techniques from Operations Research, Machine Learning and Simulation, these models are used to govern scheduling and equipment selection of hundreds of thousands of truck movements, optimize network configurations, determine the transit times between nodes, and simulate network flow under uncertainty for informed decision making. Our core team consists of Applied, Data, and Research Scientists along with technical Product Managers that come from diverse backgrounds.
  • US, WA, Seattle
    Job ID: 10526700
    (Updated 35 days ago)
    Amazon serves hundreds of millions of customers. Each one has a unique history of purchases, preferences, and behaviors. Our team's mission: turn that history into real-time contextual intelligence that makes every Amazon experience feel personal. We're hiring an Applied Scientist to push the boundaries of what's possible with LLMs, semantic retrieval, and customer understanding at scale. The problem space: Imagine a system that can instantly synthesize years of customer signals — what they bought, what they love, what they're planning — and surface the exact right context for any experience, in milliseconds. That's what we build. It's equal parts information retrieval, generative AI, and systems engineering. Why this role: 1. Scale: Your models will serve 1,500+ requests per second across Amazon's largest surfaces. 2. Impact: Direct revenue attribution in the hundreds of millions — your work shows up in customer experiences the same week. 3. Frontier tech: Fine-tuning LLMs, building custom embedding models, designing retrieval architectures that balance quality with sub-100ms latency constraints. 4. Data richness: Access to one of the most comprehensive customer behavior datasets anywhere. 5. Ownership: End-to-end — from research to production deployment to metric evaluation. Key job responsibilities 1. Invent new approaches to contextual retrieval, relevance scoring, and LLM-based summarization. 2. Fine-tune and evaluate language models for domain-specific understanding. 3. Design experiments that measure real customer impact, not just benchmark scores. 4. Ship production systems and iterate based on live metrics. 5. Collaborate across teams — Alexa, Search, Recommendations — as a platform that powers them all. 6. Mentor team members and shape the technical direction of our roadmap. Please visit https://www.amazon.science for more information. A day in the life You'll analyze large-scale behavioral data, design experiments, and build models that ship to production. You'll work closely with engineers to ensure your science translates into low-latency, high-reliability systems. You'll present findings to leadership and influence product strategy. Some weeks you'll be deep in model architecture; other weeks you'll be debugging a relevance gap in production. Every day, your work reaches real customers. About the team We're a small, high-impact team that values scientific rigor and engineering craft equally. The team values innovations and offers a safe place to try, fail and learn while fostering a culture of continuous improvement. Everyone is a leader and owner for everything we do as a team. Our team offers creative space with entrepreneurial work environment focusing on customer obsession.

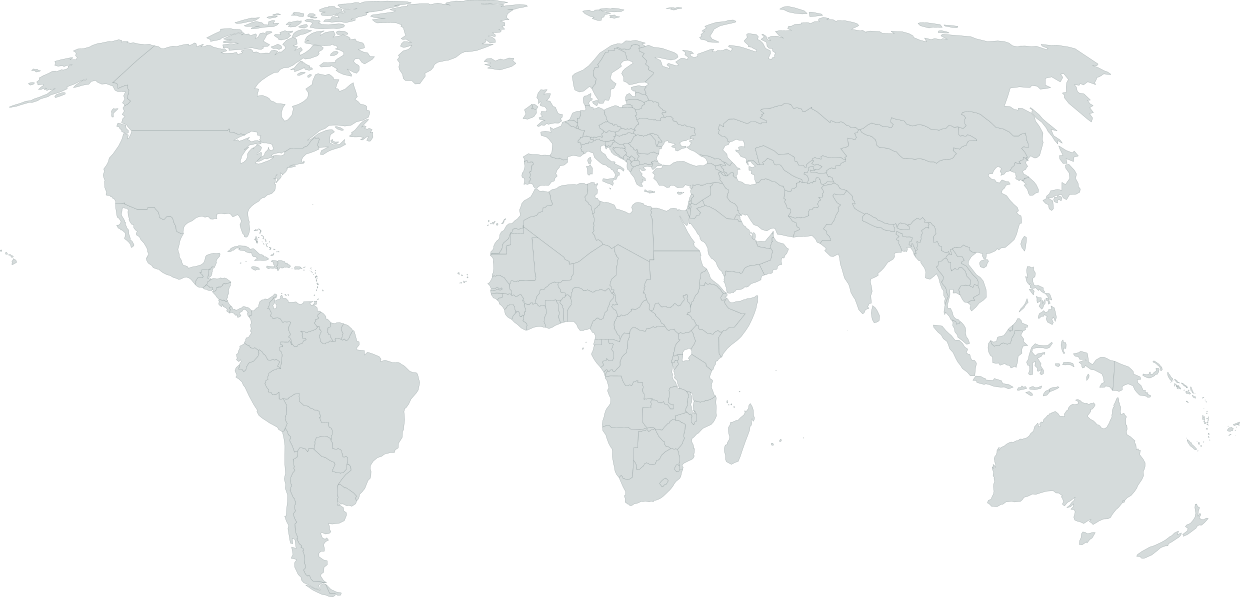
Science at Amazon around the world

Amazon scientists are working on large-scale technical challenges in a variety of research areas across the globe. Use the pins below to learn more about the customer-obsessed science being conducted at some of our research locations.
world map in greyscale
Australia
South Australia, AU
City
New South Wales, AU
City
Canada
British Columbia
City
Ontario
City
China
Shanghai, CN
City
Beijing, CN
City
Germany
City City City
India
Hyderabad, IN
City
Bengaluru, IN
City
Israel
Luxembourg
City
United Kingdom
United States
California (Southern)
California (Northern)
San Francisco
Massachusetts
New York
Pennsylvania
City
Texas
City
Virginia
Washington
download (18).jpeg

Academia

Amazon collaborates with leading academic organizations to drive innovation and to ensure that research is creating solutions whose benefits are shared broadly across all sectors of society.